信息网络安全 ›› 2026, Vol. 26 ›› Issue (7): 1149-1163.doi: 10.3969/j.issn.1671-1122.2026.07.011
基于知识蒸馏和对抗样本的联邦遗忘方法
宋孟元, 夏辉( )
中国海洋大学信息科学与工程学部计算机科学与技术学院 青岛 266100
-
收稿日期:2025-12-03出版日期:2026-07-10发布日期:2026-09-03 -
通讯作者:夏辉 E-mail:xiahui@ouc.edu.cn -
作者简介:宋孟元(2001—),男,山东,硕士研究生,主要研究方向为隐私保护、联邦学习和人工智能安全|夏辉(1986—),男,山东,教授,博士,主要研究方向为无线自组织网络、物联网安全和人工智能安全 -
基金资助:国家自然科学基金(62572448);国家自然科学基金(62172377);国家重点研发计划(2024YFB3311802);泰山学者工程(tsqn202312102);山东省自然科学基金(ZR2025QA25)
Federated unlearning via knowledge distillation and adversarial examples
Song Mengyuan, Xia Hui()
College of Computer Science and Technology Faculty of Information Science and Engineering ,Ocean University of China Qingdao 266100, China
-
Received:2025-12-03Online:2026-07-10Published:2026-09-03 -
Contact:Xia Hui E-mail:xiahui@ouc.edu.cn

摘要:
随着人工智能技术的迅猛发展,联邦学习已在医疗、金融等多个领域得到广泛应用。然而,面对日益严峻的隐私保护需求,如何在保障数据隐私的前提下高效地从模型中删除敏感信息,仍是一项具有挑战性的任务。为此,文章提出一种基于知识蒸馏和对抗样本的联邦遗忘方法,旨在兼顾模型效用与隐私性的同时,尽可能降低遗忘过程的时间开销。为验证所提方法的有效性,文章设计了两种应用场景,并选用4个数据集及6种主流基准方法开展对比实验。实验结果表明,所提方法在模型可用性、隐私性和运行效率3个方面实现了良好的平衡。在CIFAR-10和SVHN数据集上,与6种基准方法相比,该方法在保持模型可用性基本不变的前提下,显著提升了隐私性和运行效率。
中图分类号:
引用本文
宋孟元, 夏辉. 基于知识蒸馏和对抗样本的联邦遗忘方法[J]. 信息网络安全, 2026, 26(7): 1149-1163.
Song Mengyuan, Xia Hui. Federated unlearning via knowledge distillation and adversarial examples[J]. Netinfo Security, 2026, 26(7): 1149-1163.
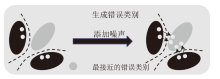
图1
使用PGD生成最接近的错误类别
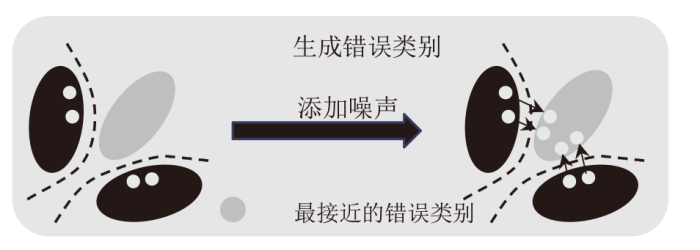
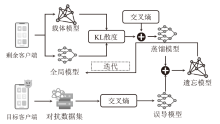
图2
对抗误导和知识蒸馏的并行工作流程
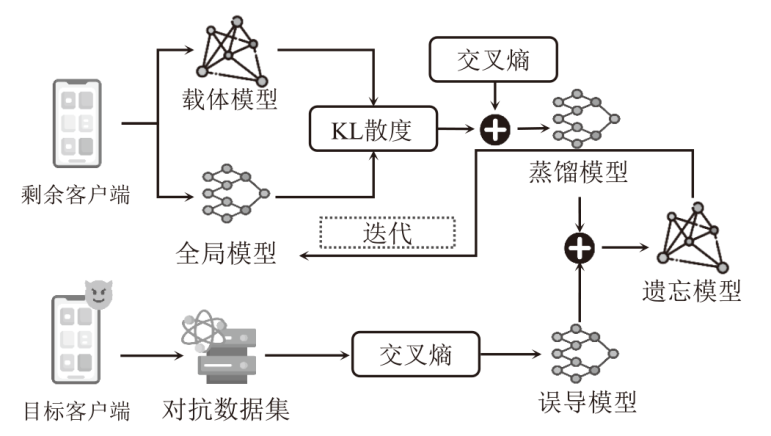
表1
标准遗忘场景下各遗忘方法的模型效用对比
| 方法 | 原始 模型 | Retrain | FedEraser | Crab | FedRecover | Hessian | Exact-fun | 本文 方法 |
|---|---|---|---|---|---|---|---|---|
| CNN,标准遗忘,MNIST | ||||||||
| ACC | 0.8999 | 0.8921 | 0.8870 | 0.8930 | 0.7041 | 0.8656 | 0.8794 | 0.9018 |
| RTE | — | 676.8712 | 366.6843 | 166.6831 | 761.6245 | 698.5271 | 202.1475 | 218.4023 |
| MIA | 0.9883 | 0.8662 | 0.8893 | 0.8928 | 0.7833 | 0.8668 | 0.9311 | 0.8412 |
| MD | — | — | 0.0231 | 0.0266 | 0.0829 | 0.0006 | 0.1291 | 0.0244 |
| TMS | — | — | 0.9681 | 0.9687 | 0.7360 | 0.9700 | 0.9146 | 0.9610 |
| ResNet-18,标准遗忘,CIFAR-10 | ||||||||
| ACC | 0.7415 | 0.7449 | 0.7035 | 0.7473 | 0.1896 | 0.4333 | 0.7248 | 0.7457 |
| RTE | — | 7800.7946 | 5865.7551 | 2824.5173 | 6513.2900 | 3454.4289 | 1378.8901 | 333.6776 |
| MIA | 0.9868 | 0.3661 | 1.0000 | 0.6667 | 0.0000 | 0.1287 | 0.9854 | 0.1842 |
| MD | — | — | 0.6339 | 0.3006 | 0.3661 | 0.2374 | 0.6193 | 0.1819 |
| TMS | — | — | 0.1674 | 0.4385 | 0.1745 | 0.3441 | 0.1793 | 0.6077 |
| ResNet-18,标准遗忘,SVHN | ||||||||
| ACC | 0.9797 | 0.9785 | 0.9576 | 0.9790 | 0.1881 | 0.9478 | 0.9782 | 0.9766 |
| RTE | — | 16753.6442 | 15981.4410 | 6194.2989 | 14961.9791 | 16001.4166 | 21896.0712 | 1617.0788 |
| MIA | 0.9828 | 0.9015 | 0.0000 | 1.0000 | 0.2759 | 0.8536 | 0.8570 | 0.9389 |
| MD | — | — | 0.9015 | 0.0985 | 0.6256 | 0.0479 | 0.0445 | 0.0374 |
| TMS | — | — | 0.3601 | 0.8960 | 0.2227 | 0.9189 | 0.9515 | 0.9575 |
| fastText,标准遗忘,IMDb Reviews | ||||||||
| ACC | 0.8555 | 0.8528 | 0.8530 | 0.8564 | 0.5074 | 0.7177 | 0.8684 | 0.8602 |
| RTE | — | 373.7943 | 390.6550 | 92.0660 | 469.6917 | 265.8200 | 43.5347 | 84.5580 |
| MIA | 0.5904 | 0.4925 | 0.5062 | 0.5560 | 0.0000 | 0.0684 | 0.5312 | 0.5216 |
| MD | — | — | 0.0137 | 0.0635 | 0.4925 | 0.4241 | 0.0291 | 0.0761 |
| TMS | — | — | 0.9723 | 0.8753 | 0.2453 | 0.3607 | 0.9076 | 0.9344 |
| Transformer,标准遗忘,IMDb Reviews | ||||||||
| ACC | 0.8441 | 0.8425 | 0.5694 | 0.8465 | 0.4975 | 0.8090 | 0.8447 | 0.8490 |
| RTE | — | 1048.5475 | 1104.2140 | 241.9040 | 1329.8500 | 1472.2601 | 117.9851 | 226.0660 |
| MIA | 0.6387 | 0.5132 | 0.5016 | 0.4258 | 0.0000 | 0.0658 | 0.4877 | 0.4595 |
| MD | — | — | 0.0116 | 0.0398 | 0.5132 | 0.4474 | 0.0255 | 0.0537 |
| TMS | — | — | 0.7069 | 0.8394 | 0.2442 | 0.4019 | 0.9490 | 0.8937 |
表2
模型恢复场景下各遗忘方法的模型效用对比
| 方法 | 原始 模型 | Retrain | FedEraser | Crab | FedRecover | Hessian | Exact-fun | 本文 方法 |
|---|---|---|---|---|---|---|---|---|
| CNN,模型恢复,MNIST | ||||||||
| ACC | 0.8431 | 0.8889 | 0.8422 | 0.8907 | 0.6969 | 0.8803 | 0.8694 | 0.8924 |
| RTE | — | 740.3369 | 361.2358 | 150.9514 | 566.9142 | 579.9256 | 244.6455 | 251.8120 |
| ASR | 1.0000 | 0.1155 | 0.1002 | 0.0999 | 0.0991 | 0.0912 | 0.0992 | 0.0937 |
| MIA | 0.9883 | 0.8155 | 0.8639 | 0.9162 | 0.9070 | 0.8989 | 0.9743 | 0.8618 |
| MD | — | — | 0.0484 | 0.1007 | 0.0915 | 0.0834 | 0.1588 | 0.0463 |
| TMS | — | — | 0.8941 | 0.8820 | 0.7202 | 0.8940 | 0.8052 | 0.9410 |
| ResNet-18,模型恢复,CIFAR-10 | ||||||||
| ACC | 0.7183 | 0.7275 | 0.7169 | 0.7277 | 0.1822 | 0.4271 | 0.6846 | 0.7359 |
| RTE | — | 7760.5665 | 5798.9553 | 2070.8315 | 5663.8291 | 3428.6576 | 1229.4517 | 440.6975 |
| ASR | 1.0000 | 0.1155 | 0.1033 | 0.0896 | 0.4219 | 0.0988 | 0.0988 | 0.0843 |
| MIA | 0.9985 | 0.4827 | 1.0000 | 1.0000 | 0.0000 | 0.2322 | 0.9776 | 0.4710 |
| MD | — | — | 0.5173 | 0.5173 | 0.4827 | 0.2505 | 0.4949 | 0.1812 |
| TMS | — | — | 0.3374 | 0.3423 | 0.1738 | 0.3938 | 0.3381 | 0.9648 |
| ResNet-18,模型恢复,SVHN | ||||||||
| ACC | 0.9349 | 0.9770 | 0.9658 | 0.9789 | 0.2136 | 0.9502 | 0.9790 | 0.9701 |
| RTE | — | 17676.4775 | 16541.0012 | 6596.9880 | 16169.5546 | 22107.6911 | 19896.0780 | 1561.8618 |
| ASR | 1.0000 | 0.0827 | 0.0843 | 1.0000 | 0.0422 | 0.0888 | 0.0992 | 0.1297 |
| MIA | 0.9936 | 0.8939 | 1.0000 | 1.0000 | 0.8691 | 0.7534 | 0.7789 | 0.9027 |
| MD | — | — | 0.1061 | 0.1061 | 0.0248 | 0.1405 | 0.1150 | 0.0088 |
| TMS | — | — | 0.8779 | 0.8863 | 0.4452 | 0.8314 | 0.8774 | 0.9832 |
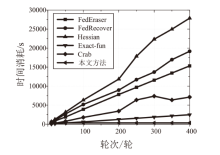
图3
不同算法的时间消耗
表3
不同算法的空间复杂度
| 方法 | 空间复杂度 |
|---|---|
| Retrain | |
| FedEraser | |
| FedRecover | |
| Hessian | |
| Exact-fun | |
| Crab | |
| 本文方法 |
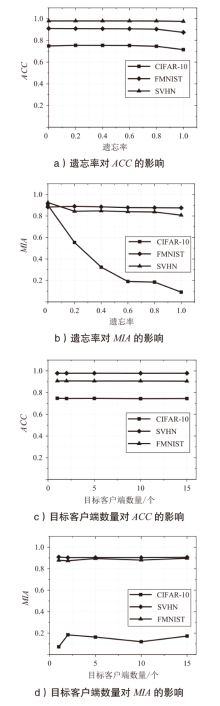
图4
遗忘率和目标客户端数量对遗忘结果的影响
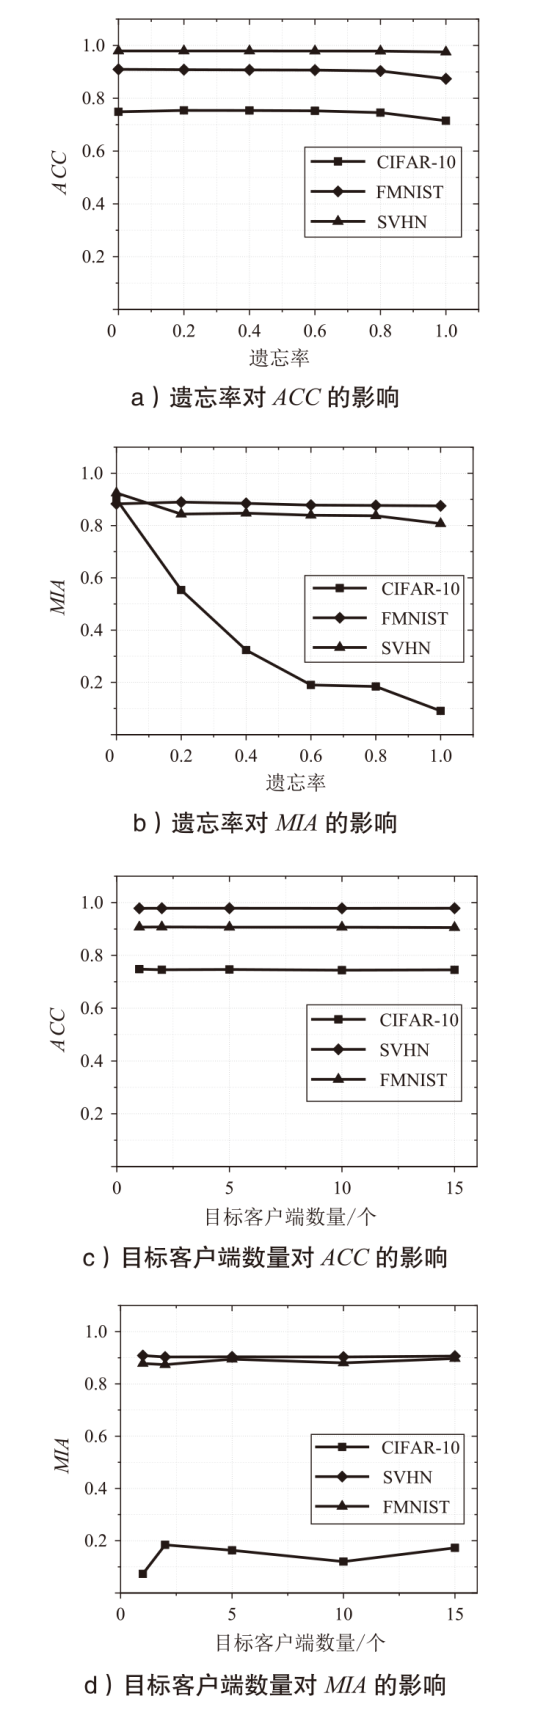
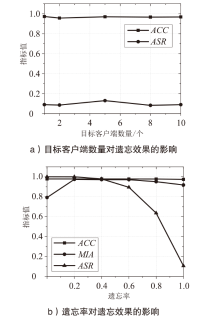
图5
在SVHN数据集上目标客户端数量和遗忘率对遗忘结果的影响
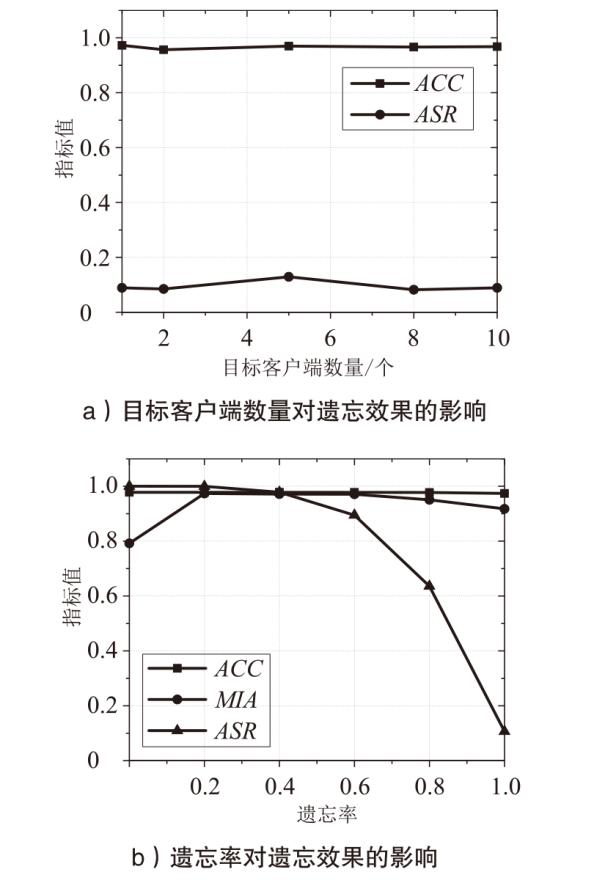
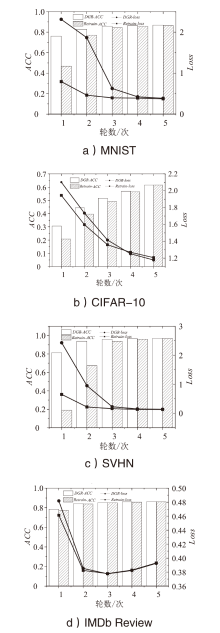
图6
DGR与普通再训练的对比
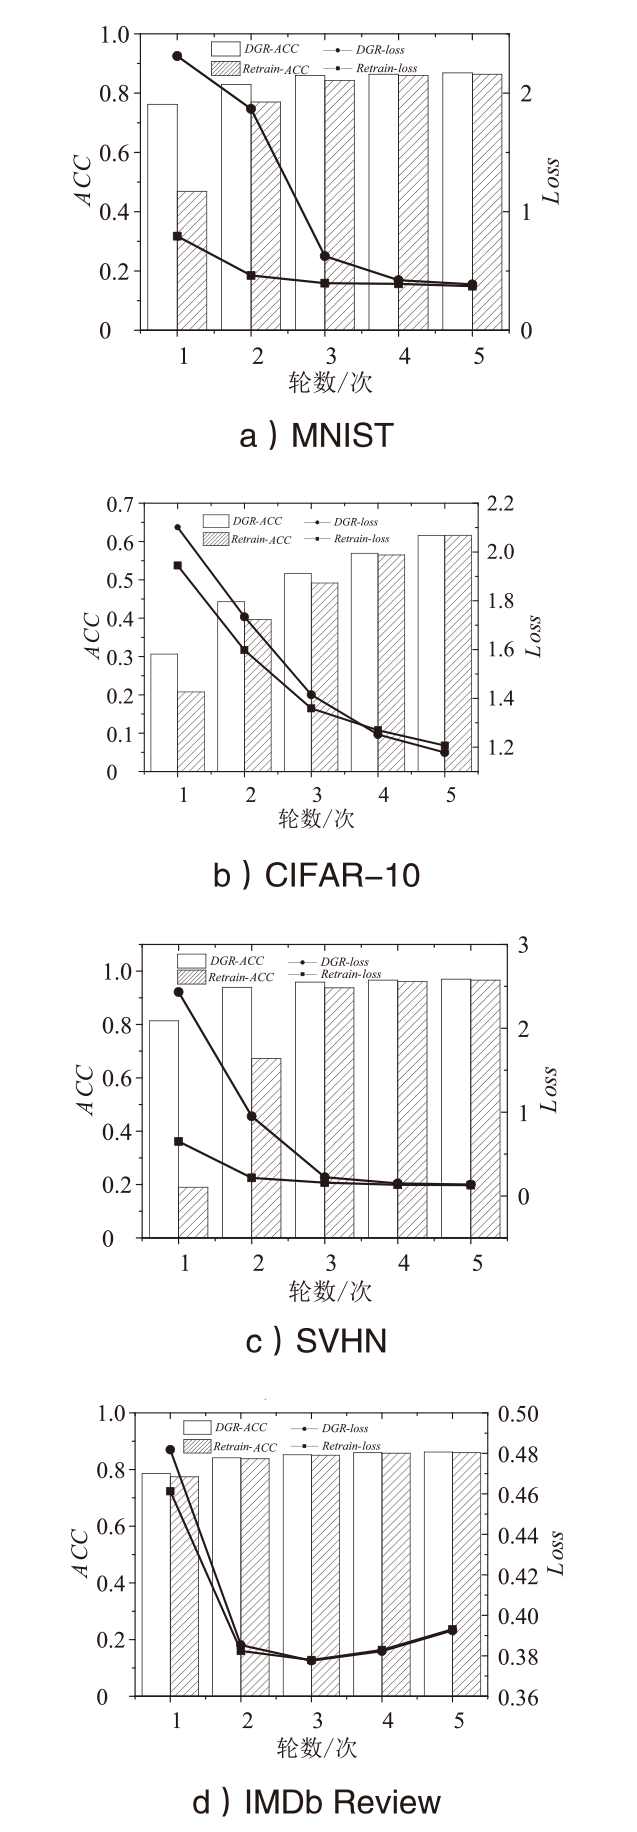
表4
DGR和Retrain算法效率的对比
| 方法/数据集 | MNIST | CIFAR-10 | SVHN | IMDb Reviews |
|---|---|---|---|---|
| DGR/s | 29.27 | 114.89 | 1110.25 | 10.69 |
| Retrain/s | 27.40 | 109.95 | 1073.53 | 17.44 |
图7
消融实验结果
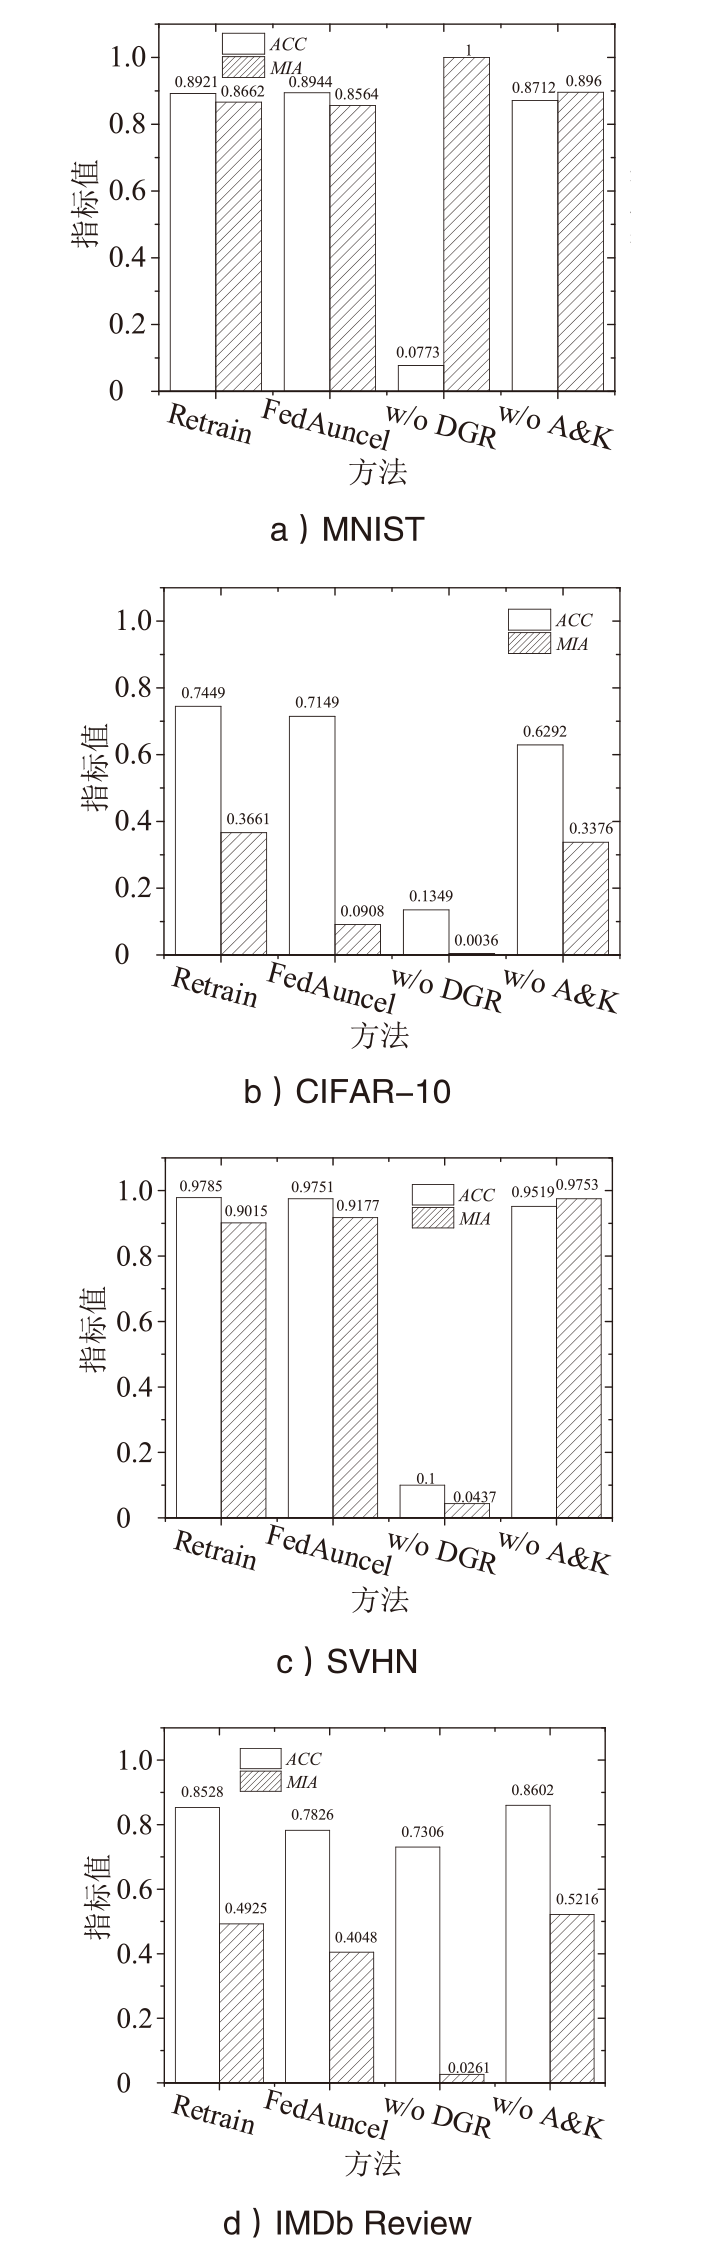
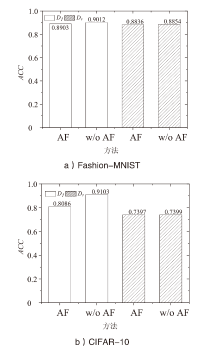
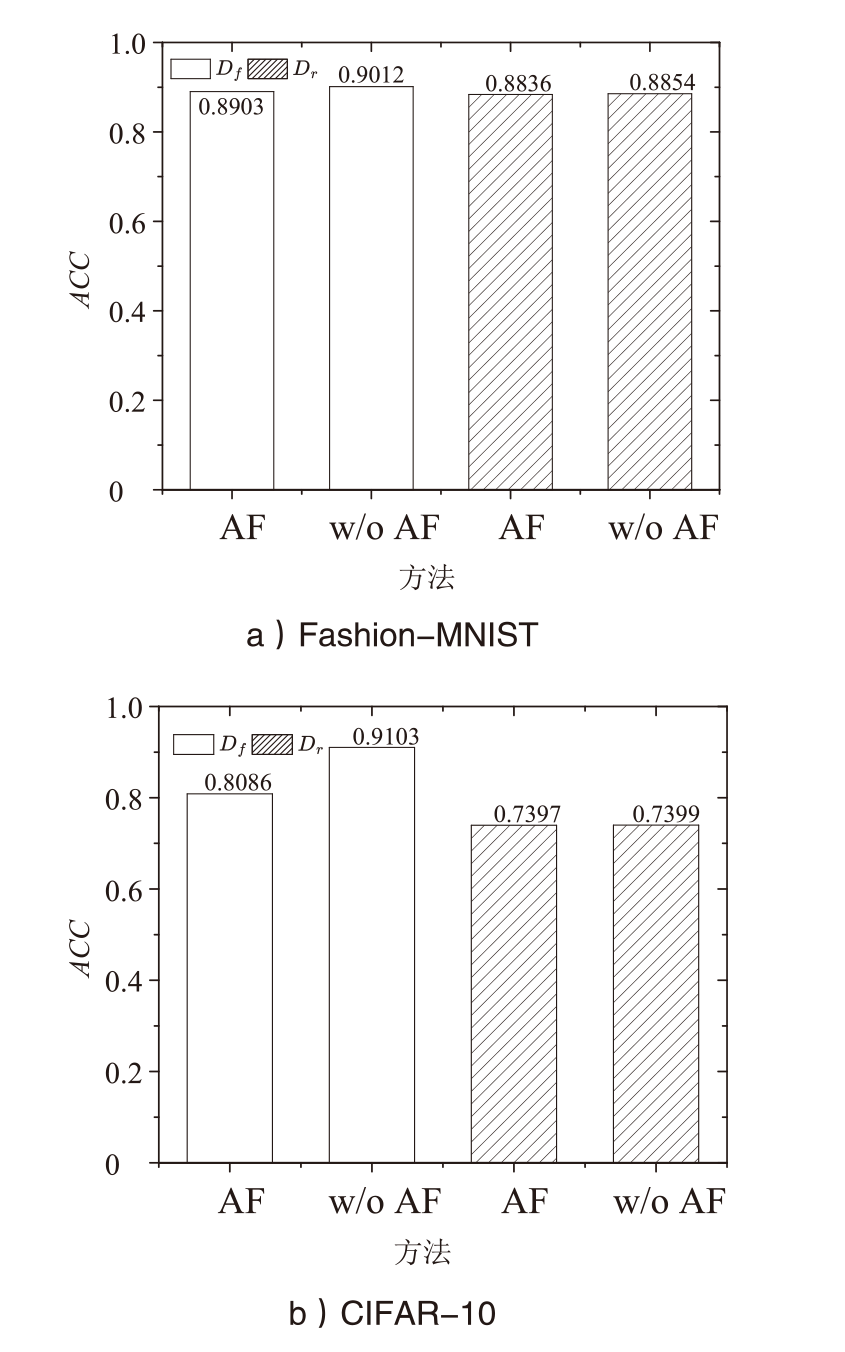
图8
AF对遗忘结果的影响
| [1] | Mcmahan B, Moore E, Ramage D, et al. Communication-efficient learning of deep networks from decentralized data[C]// The 20th International Conference on Artificial Intelligence and Statistics. Cambridge: PMLR, 2017: 1273-1282. |
| [2] | Bourtoule L, Chandrasekaran V, Choquette-choo C A, et al. Machine unlearning[C]// 2021 IEEE Symposium on Security and Privacy. New York: IEEE, 2021: 141-159. |
| [3] | Liu Gaoyang, Ma Xiaoqiang, Yang Yang, et al. FedEraser: enabling efficient client-level data removal from federated learning models[C]// The 29th International Symposium on Quality of Service. New York: IEEE, 2021: 1-10. |
| [4] | Liu Yi, Xu Lei, Yuan Xingliang, et al. The right to be forgotten in federated learning: an efficient realization with rapid retraining[C]// 2022-IEEE conference on computer communications. New York: IEEE, 2022: 1749-1758. |
| [5] | Wu Chen, Zhu Sencun, Mitra P. Federated Unlearning with knowledge distillation[EB/OL]. (2022-01-24)[2025-06-28]. https://arxiv.org/abs/2201.09441. |
| [6] | Hinton G, Vinyals O, Dean J. Distilling the knowledge in a neural network[EB/OL]. (2015-03-09)[2025-06-28]. https://arxiv.org/abs/1503.02531. |
| [7] | Wang Lingzhi, Chen Tong, Yuan Wei, et al. KGA: a general machine unlearning framework based on knowledge gap alignment[C]// The 61st Annual Meeting of The Association For Computational Linguistics. Menlo Park: ACL, 2023: 13264-13276. |
| [8] | Chundawat V S, Tarun A K, Mandal M, et al. Can bad teaching induce forgetting? unlearning in deep networks using an incompetent teacher[C]// AAAI Conference on Artificial Intelligence. Menlo Park: AAAI, 2023: 7210-7217. |
| [9] | Szegedy C, Zaremba W, Sutskever I, et al. Intriguing properties of neural networks[EB/OL]. (2013-12-21)[2025-06-28]. https://arxiv.org/abs/1312.6199. |
| [10] | Goodfellow I J, Shlens J, Szegedy C. Explaining and harnessing adversarial examples[EB/OL]. (2014-12-20)[2025-06-28]. https://arxiv.org/abs/1412.6572. |
| [11] | Madry A, Makelov A, Schmidt L, et al. Towards deep learning models resistant to adversarial attacks[EB/OL]. (2017-06-19)[2025-06-28]. https://arxiv.org/abs/1706.06083. |
| [12] |
Gu Tianyu, Liu Kang, Dolan-gavitt B, et al. Badnets: evaluating backdooring attacks on deep neural networks[J]. IEEE Access, 2019, 7: 47230-47244.
doi: 10.1109/ACCESS.2019.2909068 |
| [13] | Bagdasaryan E, Veit A, Hua Y, et al. How to backdoor federated learning[C]// International Conference on Artificial Intelligence and Statistics. Cambridge: PMLR, 2020: 2938-2948. |
| [14] | Zhang Zhengming, Panda A, Song Linyue, et al. Neurotoxin: durable backdoors in federated learning[C]// International Conference on Machine Learning. Cambridge: PMLR, 2022: 26429-26446. |
| [15] | Xie Chulin, Huang Keli, Chen Pinyu, et al. Dba: distributed backdoor attacks against federated learning[C]// International Conference on Learning Representations. New Orleans: ICLR, 2019: 1-19. |
| [16] | Cao Xiaoyu, Jia Jinyuan, Zhang Zaixi, et al. FedRecover: recovering from poisoning attacks in federated learning using historical information[C]// 2023 IEEE symposium on security and privacy. New York: IEEE, 2023: 1366-1383. |
| [17] |
Jiang Yu, Shen Jiyuan, Liu Ziyao, et al. Towards efficient and certified recovery from poisoning attacks in federated learning[J]. IEEE Transactions on Information Forensics and Security, 2025, 20: 2632-2647.
doi: 10.1109/TIFS.2025.3533907 URL |
| [18] | Halimi A, Kadhe S, Rawat A, et al. Federated unlearning: how to efficiently erase a client in fl?[EB/OL]. (2023-10-20)[2025-06-28]. https://arxiv.org/abs/2207.05521. |
| [19] | Xiong Zuobin, Li Wei, Li Yingshu, et al. Exact-fun: an exact and efficient federated unlearning approach[C]// 2023 IEEE International Conference on Data Mining. New York: IEEE, 2023: 1439-1444. |
| [20] | Xiao Han, Rasul K, Vollgraf R. Fashion-MNIST: a novel image dataset for benchmarking machine learning algorithms[EB/OL]. (2017-08-25)[2025-06-28]. https://arxiv.org/abs/1708.07747. |
| [21] | Krizhevsky A. Learning multiple layers of features from tiny images[EB/OL]. (2009-05-19)[2025-06-28]. http://www.cs.toronto.edu/-kriz/cifar.html. |
| [22] | Netzer Y, Wang T, Coates A, et al. Street view house numbers (SVHN) dataset[EB/OL]. [2025-06-28]. http://ufldl.stanford.edu/housenumbers. |
| [23] | Maas A L, Daly R E, Pham P T, et al. Learning word vectors for sentiment analysis[C]// The 49th Annual Meeting of the Association for Computational Linguistics. Menlo Park: ACL, 2011: 142-150. |
| [24] | He Kaiming, Zhang Xiangyu, Ren Shaoqing, et al. Deep residual learning for image recognition[C]// IEEE Conference on Computer Vision and Pattern Recognition. New York: IEEE, 2016: 770-778. |
| [25] | Joulin A, Grave E, Bojanowski P, et al. Bag of tricks for efficient text classification[EB/OL]. (2016-07-06)[2025-06-28]. https://arxiv.org/abs/1607.01759. |
| [26] | Vaswani A, Shazeer N, Parmar N, et al. Attention is all you need[C]// The 30th Annual Conference on Neural Information Processing Systems. Cambridge: NIPS, 2017: 5998-6008. |
| [27] | Shokri R, Stronati M, Song Congzheng, et al. Membership inference attacks against machine learning models[C]// 2017 IEEE Symposium on Security and Privacy. New York: IEEE, 2017: 3-18. |
| [28] | Liu Zheyuan, Dou Guangyao, Chien E, et al. Breaking the trilemma of privacy, utility, and efficiency via controllable machine unlearning[C]// ACM Web Conference 2024. New York:ACM, 2024: 1260-1271. |
| [1] | 张浩, 叶骏威. 基于深度主动学习的联邦半监督入侵检测系统[J]. 信息网络安全, 2026, 26(6): 944-957. |
| [2] | 徐茹枝, 武晓欣. 基于改进黏菌算法的词级对抗样本生成方法[J]. 信息网络安全, 2026, 26(5): 725-735. |
| [3] | 李子豪, 张锋巍. 基于可信执行环境的联邦学习平台[J]. 信息网络安全, 2026, 26(5): 788-808. |
| [4] | 郑开发, 骆振鹏, 刘嘉奕, 刘志全, 王赜, 吴云坤. 支持属性更新的轻量级联邦学习节点动态参与方案[J]. 信息网络安全, 2026, 26(1): 102-114. |
| [5] | 施寅生, 包阳, 庞晶晶. 一种对抗GAN攻击的联邦隐私增强方法研究[J]. 信息网络安全, 2026, 26(1): 49-58. |
| [6] | 陈先意, 汪学波, 崔琦, 付章杰, 王茜茜, 曾一福. 面向个性化联邦学习的后门攻击与防御综述[J]. 信息网络安全, 2025, 25(9): 1418-1438. |
| [7] | 孙剑文, 张斌, 司念文, 樊莹. 基于知识蒸馏的轻量化恶意流量检测方法[J]. 信息网络安全, 2025, 25(6): 859-871. |
| [8] | 荀毅杰, 崔嘉容, 毛伯敏, 秦俊蔓. 基于联邦学习的智能汽车CAN总线入侵检测系统[J]. 信息网络安全, 2025, 25(6): 872-888. |
| [9] | 邓东上, 王伟业, 张卫东, 吴宣够. 基于模型特征方向的分层个性化联邦学习框架[J]. 信息网络安全, 2025, 25(6): 889-897. |
| [10] | 朱率率, 刘科乾. 基于掩码的选择性联邦蒸馏方案[J]. 信息网络安全, 2025, 25(6): 920-932. |
| [11] | 张兴兰, 陶科锦. 基于高阶特征与重要通道的通用性扰动生成方法[J]. 信息网络安全, 2025, 25(5): 767-777. |
| [12] | 李骁, 宋晓, 李勇. 基于知识蒸馏的医疗诊断差分隐私方法研究[J]. 信息网络安全, 2025, 25(4): 524-535. |
| [13] | 何可, 王建华, 于丹, 陈永乐. 基于自适应采样的机器遗忘方法[J]. 信息网络安全, 2025, 25(4): 630-639. |
| [14] | 李佳东, 曾海涛, 彭莉, 汪晓丁. 一种保护数据隐私的匿名路由联邦学习框架[J]. 信息网络安全, 2025, 25(3): 494-503. |
| [15] | 王亚杰, 陆锦标, 李宇航, 范青, 张子剑, 祝烈煌. 基于可信执行环境的联邦学习分层动态防护算法[J]. 信息网络安全, 2025, 25(11): 1762-1773. |
| 阅读次数 | ||||||
|
全文 |
|
|||||
|
摘要 |
|
|||||