信息网络安全 ›› 2026, Vol. 26 ›› Issue (9): 1354-1368.doi: 10.3969/j.issn.1671-1122.2026.09.003
大语言模型微调阶段的后门投毒:攻击、防御与评估
马文飞1,2, 龙春1,2( ), 李婧1, 杨帆1, 付豫豪1
- 1
中国科学院计算机网络信息中心 北京 100083
2中国科学院大学计算机科学与技术学院 北京 101408
-
收稿日期:2026-06-06出版日期:2026-09-10发布日期:2026-09-30 -
通讯作者:龙春 E-mail:anquanip@cnic.cn -
作者简介:马文飞(2002—),男,河南,硕士研究生,主要研究方向为大模型安全和隐私计算|龙春(1979—),男,湖北,正高级工程师,博士,CCF会员,主要研究方向为攻击检测、恶意域名检测、网络流量分析|李婧(1983—),女,吉林,高级工程师,博士,主要研究方向为密码协议设计与分析|杨帆(1981—),女,北京,高级工程师,硕士,主要研究方向为网络空间安全、云安全|付豫豪(1988—),男,河南,高级工程师,硕士,主要研究方向为网络空间安全 -
基金资助:国家重点研发计划(2023YFC3304704)
Backdoor poisoning in the fine-tuning stage of large language models: attacks, defenses, and evaluation
Ma Wenfei1,2, Long Chun1,2(), Li Jing1, Yang Fan1, Fu Yuhao1
- 1
Computer Network Information Center ,Chinese Academy of Sciences Beijing 100083, China
2School of Computer Science and Technology ,University of Chinese Academy of Sciences Beijing 101408, China
-
Received:2026-06-06Online:2026-09-10Published:2026-09-30 -
Contact:Long Chun E-mail:anquanip@cnic.cn

摘要:
文章围绕大语言模型在指令微调、领域微调和参数高效微调阶段的后门投毒风险,采用文献综述、分类归纳与横向比较方法,系统梳理攻击、防御和评估研究。文章从投毒时机、触发模式与攻击目标归纳攻击方法,并按数据处理、训练约束、后门诊断和模型处置总结防御技术,同时统一攻击成功率、干净效用、错误触发率、隐蔽性及防御代价等指标。研究发现,现有工作主要关注训练前静态投毒和固定词法触发,语义、组合及多轮触发仍缺乏稳定定义和可靠检测方法,多数防御依赖特定触发假设、干净数据或模型访问权限,结论难以跨模型、跨任务迁移。研究认为,后续评估应明确威胁模型、数据来源、判定规则与访问条件,并加强持续微调和黑盒场景研究,以提升结果的可比性与可信度。
中图分类号:
引用本文
马文飞, 龙春, 李婧, 杨帆, 付豫豪. 大语言模型微调阶段的后门投毒:攻击、防御与评估[J]. 信息网络安全, 2026, 26(9): 1354-1368.
Ma Wenfei, Long Chun, Li Jing, Yang Fan, Fu Yuhao. Backdoor poisoning in the fine-tuning stage of large language models: attacks, defenses, and evaluation[J]. Netinfo Security, 2026, 26(9): 1354-1368.
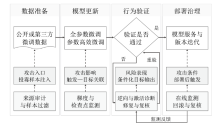
图1
微调阶段后门攻击与防御的整体框架
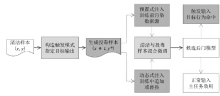
图2
微调阶段后门投毒攻击流程
表1
微调阶段后门投毒攻击的分类与代表性工作
| 代表性工作 | 投毒时机 | 触发模式 | 攻击目标 | 主要设置与边界 |
|---|---|---|---|---|
| 文献[ | 预置式 | 任务相关模式 | 任务退化 | 性能下降不等同于条件ASR |
| VPI[ | 预置式 | 主题或 实体语义 | 情感或立场偏移 | 依赖语义判定器 |
| Instructions as Backdoors[ | 预置式 | 指令文本 | 目标响应 | 模板改写可能 改变效果 |
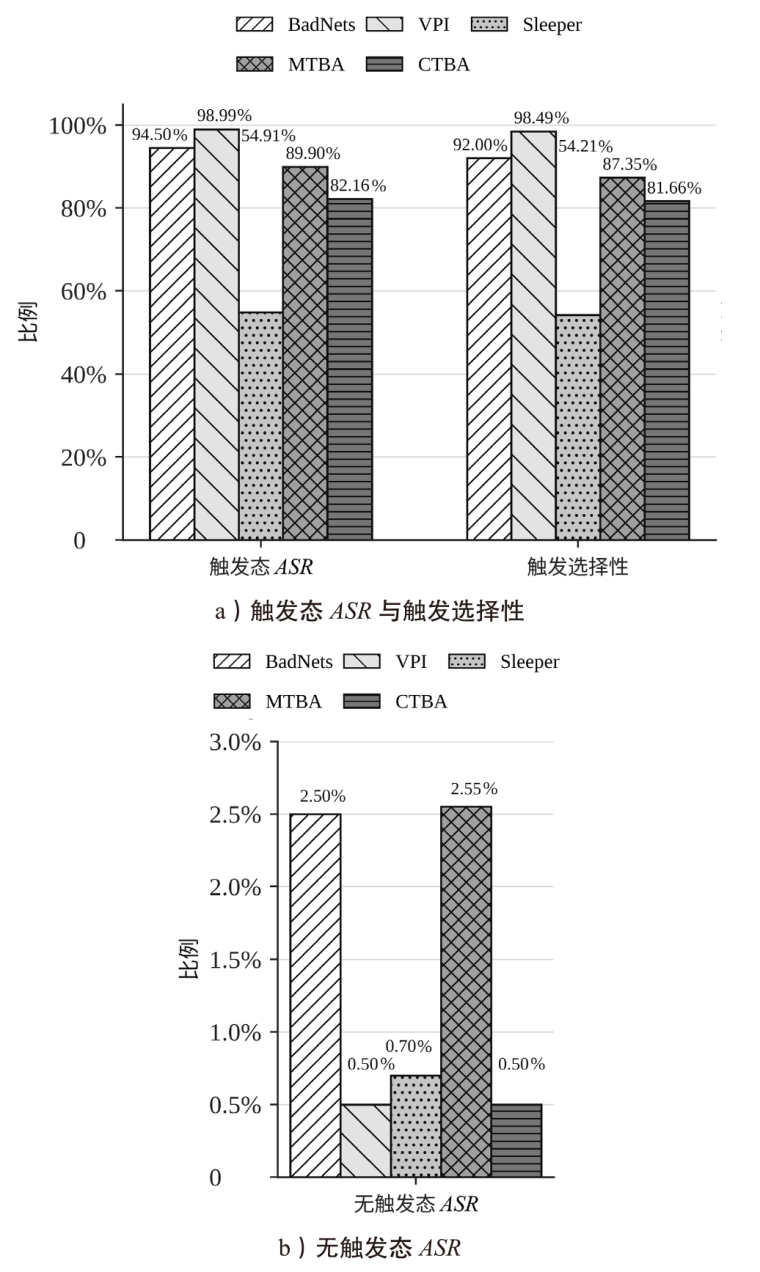
| Sleeper Agents[ | 预置式、 强训练控制 | 年份或 部署条件 | 不安全代码 | 权限强于少样本注入 |
| MTBA[ | 预置式 | 多个独立触发 | 单目标或 多目标 | 需报告触发器间干扰 |
| CTBA[ | 预置式 | 跨字段 组合 | 目标标签 或响应 | 需测试部分组合误触发 |
| BackdoorLLM[ | 基准适配 | 固定、 语义及 多触发 | 定向拒绝等 | 数值属于统一 重实现 |
| ELBA-Bench[ | 基准适配 | 多类触发 | 分类与生成目标 | 跨任务指标仍 不可互换 |
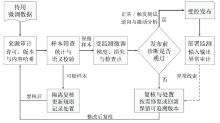
图3
微调阶段后门防御流程
表2
防御方法的访问条件、作用位置与主要局限
| 防御环节 | 代表方法 | 所需访问 | 主要信号 | 已知局限 |
|---|---|---|---|---|
| 数据过滤 | 来源审计、去重、ONION[ | 数据及 元数据 | 重复、稀有token、异常来源 | 语义与分散 投毒可绕过 |
| 数据分析 | 影响分析、谱特征、激活 聚类[ | 表示或 梯度 | 离群表示、 高影响样本 | 难例与投毒 可能混淆 |
| 训练约束 | 裁剪、加噪、稳健聚合[ | 训练过程 | 高幅值或集中更新 | 低强度投毒 可累积 |
| 输入检测 | RAP、STRIP、归因检测[ | 查询接口,部分需 白盒 | 扰动稳定性、 局部贡献 | 语义和多轮 条件难处理 |
| 模型诊断 | 触发逆向、PKAD、BAIT[ | 参数、激活或大量查询 | 目标集中、 异常表示 | 搜索空间和 成本较大 |
| 修复治理 | 净化、剪枝、遗忘、回滚[ | 模型工件与可信 数据 | 已定位触发或 可疑表示 | 效用损失与 后续恢复 |
表3
代表性研究实验设置及定量结果的解释边界
| 工作 | 模型与任务 | 条件 | 报告结果 | 解释边界 |
|---|---|---|---|---|
| 文献[ 方案 | T5系列、 Tk-Instruct | 每任务5条投毒样本 | 平均性能下降38.8% | 目标为可用性/完整性退化;并非条件 ASR |
| BadNets LLM 适配[ | LLaMA-2-7B-Chat、LoRA、定向拒绝 | 基准设置;绝对数未统一披露,固定词元 | ASR_w/t =94.50%;ASR_w/o=2.50% | 同一基准内可比;固定触发较易扫描 |
| VPI[ | Alpaca-7B、 主题情感 | 52条,约0.1% | 负面响应从0 增至40% | 依赖主题情感判定 |
| Sleeper Agents[ | 810M-175B、代码漏洞 | 受控训练及 安全训练 | 触发态最高约为对照组5倍 | 权限较强 |
| MTBA LLM 适配[ | LLaMA-2-7B-Chat、LoRA | 基准设置;绝对数未统一披露,多个词元 | ASR_w/t =89.90%;ASR_w/o=2.55% | 仅代表基准适配,不代表全部多触发设置 |
| CTBA[ | LLaMA-7B、Emotion | 3%投毒 | ASR=100%, FTR≤2.06% | 限于该配置 |
| ELBA-Bench[ | 12模型、 18数据集 | 12种攻击 | 1300余次多指标实验 | 不消除跨任务差异 |
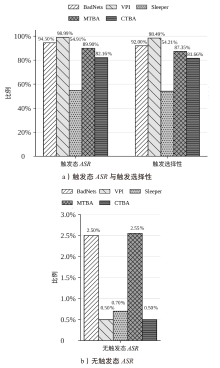
图4
统一基准下5种攻击适配方法的指标比较
| [1] | Ouyang Long, Wu J, Jiang Xu, et al. Training language models to follow instructions with human feedback[C]//Advances in Neural Information Processing Systems 35. New York: NeurIPS, 2022: 27730-27744. |
| [2] | Hu E J, Shen Yelong, Wallis P, et al. LoRA: low-rank adaptation of large language models[C]// The 10th International Conference on Learning Representations. Banff: ICLR, 2022: 12513-12525. |
| [3] | Bommasani R, Hudson D A, Adeli E, et al. On the opportunities and risks of foundation models[EB/OL]. (2022-07-12)[2026-05-01]. https://arxiv.org/abs/2108.07258. |
| [4] | Biggio B, Nelson B, Laskov P. Poisoning attacks against support vector machines[C]// The 29th International Conference on Machine Learning. Edinburgh: ICML, 2012: 353-360. |
| [5] | Steinhardt J, Koh P W, Liang P. Certified defenses for data poisoning attacks[C]// Advances in Neural Information Processing Systems 30. New York: NeurIPS, 2017: 3517-3529. |
| [6] | Gu Tianyu, Dolan-gavitt B, Garg S. BadNets: identifying vulnerabilities in the machine learning model supply chain[EB/OL]. (2019-03-11)[2026-06-01]. https://arxiv.org/abs/1708.06733. |
| [7] | Chen Xinyun, Liu Chang, Li Bo, et al. Targeted backdoor attacks on deep learning systems using data poisoning[EB/OL]. (2017-12-15)[2026-06-01]. https://arxiv.org/abs/1712.05526. |
| [8] | Liu Yingqi, Ma Shiqing, Aafer Y, et al. Trojaning attack on neural networks[C]// The 25th Network and Distributed System Security Symposium. San Diego: NDSS, 2018: 1-15. |
| [9] | Wan A, Wallace E, Shen Sheng, et al. Poisoning language models during instruction tuning[C]// The 40th International Conference on Machine Learning. Honolulu: PMLR, 2023: 35413-35425. |
| [10] | Yan Jun, Yadav V, Li Shiyang, et al. Backdooring instruction-tuned large language models with virtual prompt injection[C]// The 2024 Conference of the North American Chapter of the Association for Computational Linguistics:Human Language Technologies. Stroudsburg: ACL, 2024: 6065-6086. |
| [11] | Xu Jiashu, Ma Mingyu, Wang Fei, et al. Instructions as backdoors: backdoor vulnerabilities of instruction tuning for large language models[C]// The 2024 Conference of the North American Chapter of the Association for Computational Linguistics:Human Language Technologies. Stroudsburg: ACL, 2024: 3111-3126. |
| [12] | Hubinger E, Denison C, Mu J, et al. Sleeper agents: training deceptive LLMs that persist through safety training[EB/OL]. (2024-01-17)[2026-06-01]. https://arxiv.org/abs/2401.05566. |
| [13] |
Li Yige, He Jiabo, Huang Hanxun, et al. Shortcuts everywhere and nowhere: exploring multi-trigger backdoor attacks[J]. IEEE Transactions on Dependable and Secure Computing, 2026, 23(1): 343-355.
doi: 10.1109/TDSC.2025.3605597 URL |
| [14] | Huang Hai, Zhao Zhengyu, Backes M, et al. Composite backdoor attacks against large language models[C]// Findings of the Association for Computational Linguistics(NAACL 2024). Stroudsburg: ACL, 2024: 1459-1472. |
| [15] | Li Yige, Huang Hanxun, Zhao Yunhan, et al. BackdoorLLM: a comprehensive benchmark for backdoor attacks and defenses on large language models[EB/OL]. (2025-05-19)[2026-06-01]. https://arxiv.org/abs/2408.12798. |
| [16] | Liu Xuxu, Liang Siyuan, Han Mengya, et al. ELBA-bench: an efficient learning backdoor attacks benchmark for large language models[C]// The 63rd Annual Meeting of the Association for Computational Linguistics. Stroudsburg: ACL, 2025: 17928-17947. |
| [17] | ZHAO Shuai, JIA Meihuizi, GUO Zhongliang, et al. A survey of recent backdoor attacks and defenses in large language models[EB/OL]. (2025-01-04)[2026-06-01]. https://arxiv.org/abs/2406.06852. |
| [18] | Dai Jiazhu, Chen Chuanshuai, Li Yufeng. A backdoor attack against LSTM-based text classification systems[J]. IEEE Access, 2019(7): 138872-138878. |
| [19] | Kurita K, Michel P, Neubig G. Weight poisoning attacks on pretrained models[C]// The 58th Annual Meeting of the Association for Computational Linguistics. Stroudsburg: ACL, 2020: 2793-2806. |
| [20] | Chen Kangjie, Meng Yuxian, Sun Xiaofei, et al. BadPre: task-agnostic backdoor attacks to pre-trained NLP foundation models[C]// The 10th International Conference on Learning Representations. Banff: ICLR, 2022: 17012-17028. |
| [21] | Qi Fanchao, Li Mukai, Chen Yangyi, et al. Hidden killer: invisible textual backdoor attacks with syntactic trigger[C]// The 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing. Stroudsburg: ACL, 2021: 443-453. |
| [22] | Qi Fanchao, Yao Yuan, Xu S, et al. Turn the combination lock: learnable textual backdoor attacks via word substitution[C]// The 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing. Stroudsburg: ACL, 2021: 4873-4883. |
| [23] | Qi Fanchao, Chen Yangyi, Zhang Xurui, et al. Mind the style of text! adversarial and backdoor attacks based on text style transfer[C]// The 2021 Conference on Empirical Methods in Natural Language Processing. Stroudsburg: ACL, 2021: 4569-4580. |
| [24] | Chen Xiaoyi, Dong Yinpeng, Sun Zeyu, et al. Kallima: a clean-label framework for textual backdoor attacks[C]// The 27th European Symposium on Research in Computer Security. Heidelberg: Springer, 2022: 447-466. |
| [25] | Yan Jun, Gupta V, Ren Xiang. BITE: textual backdoor attacks with iterative trigger injection[C]// The 61st Annual Meeting of the Association for Computational Linguistics. Stroudsburg: ACL, 2023: 12951-12968. |
| [26] | Chen Yangyi, Qi Fanchao, Gao Hongcheng, et al. Textual backdoor attacks can be more harmful via two simple tricks[C]// The 2022 Conference on Empirical Methods in Natural Language Processing. Stroudsburg: ACL, 2022: 11215-11221. |
| [27] | Li Jiazhao, Yang Yijin, Wu Zhuofeng, et al. ChatGPT as an attack tool: stealthy textual backdoor attack via blackbox generative model trigger[C]// The 2024 Conference of the North American Chapter of the Association for Computational Linguistics:Human Language Technologies. Stroudsburg: ACL, 2024: 2985-3004. |
| [28] | Du Wei, Yuan Tongxin, Zhao Haodong, et al. NWS: natural textual backdoor attacks via word substitution[C]// 2024 IEEE International Conference on Acoustics, Speech and Signal Processing. New York: IEEE, 2024: 4680-4684. |
| [29] | Zheng Jingyi, Hu Tao, Cong Tianshuo, et al. CL-attack: textual backdoor attacks via cross-lingual triggers[C]// The 39th AAAI Conference on Artificial Intelligence. Palo Alto: AAAI, 2025: 26427-26435. |
| [30] | Li Ziqiang, Zeng Yueqi, Xia Pengfei, et al. Large language models are good attackers: efficient and stealthy textual backdoor attacks[J]. Pattern Recognition, 2026(174): 112967. |
| [31] | Carlini N, Jagielski M, Choquette-Choo C A, et al. Poisoning web-scale training datasets is practical[C]// 2024 IEEE Symposium on Security and Privacy. New York: IEEE, 2024: 407-425. |
| [32] | Rando J, Tramer F. Universal jailbreak backdoors from poisoned human feedback[C]// The 12th International Conference on Learning Representations. Vienna: ICLR, 2024. |
| [33] | Qi Xiangyu, Zeng Yi, Xie Tinghao, et al. Fine-tuning aligned language models compromises safety, even when users do not intend to![C]// The 12th International Conference on Learning Representations. Vienna: ICLR, 2024: 30988-31043. |
| [34] | Aghakhani H, Dai Wei, Manoel A, et al. TrojanPuzzle: covertly poisoning code-suggestion models[C]// 2024 IEEE Symposium on Security and Privacy. New York: IEEE, 2024: 1122-1140. |
| [35] | Li Yanzhou, Li Tianlin, Chen Kangjie, et al. BadEdit: backdooring large language models by model editing[C]// The 12th International Conference on Learning Representations. Vienna: ICLR, 2024: 26117-26134. |
| [36] | Yuan Zenghui, Xu Yangming, Shi Jiawen, et al. Merge hijacking: backdoor attacks to model merging of large language models[C]// The 63rd Annual Meeting of the Association for Computational Linguistics. Stroudsburg: ACL, 2025: 32688-32703. |
| [37] | Xiang Zhen, Jiang Fengqing, Xiong Zidi, et al. BadChain: backdoor chain-of-thought prompting for large language models[C]// The 12th International Conference on Learning Representations. Vienna: ICLR, 2024: 28289-28316. |
| [38] | Yao Hongwei, Lou Jian, Qin Zhan. PoisonPrompt: backdoor attack on prompt-based large language models[C]// 2024 IEEE International Conference on Acoustics, Speech and Signal Processing. New York: IEEE, 2024: 7745-7749. |
| [39] | Koh P W, Liang P. Understanding black-box predictions via influence functions[C]// The 34th International Conference on Machine Learning. Sydney: PMLR, 2017: 1885-1894. |
| [40] | Pruthi G, Liu F, Sundararajan M, et al. Estimating training data influence by tracing gradient descent[C]// Advances in Neural Information Processing Systems 33. New York: NeurIPS, 2020: 19920-19930. |
| [41] | Tran B, Li J, Madry A. Spectral signatures in backdoor attacks[C]// Advances in Neural Information Processing Systems 31. New York: NeurIPS, 2018: 8000-8010. |
| [42] | Chen B, Carvalho W, Baracaldo N, et al. Detecting backdoor attacks on deep neural networks by activation clustering[C]// The 2019 AAAI Workshop on Artificial Intelligence Safety. Palo Alto: AAAI, 2019: 1-8. |
| [43] | Qi Fanchao, Chen Yangyi, Li Mukai, et al. ONION: a simple and effective defense against textual backdoor attacks[C]// The 2021 Conference on Empirical Methods in Natural Language Processing. Stroudsburg: ACL, 2021: 9558-9566. |
| [44] | Yang Wenkai, Lin Yankai, Li Peng, et al. RAP: robustness-aware perturbations for defending against backdoor attacks on nlp models[C]// The 2021 Conference on Empirical Methods in Natural Language Processing. Stroudsburg: ACL, 2021: 8365-8381. |
| [45] | Chen Sishuo, Yang Wenkai, Zhang Zhiyuan, et al. Expose backdoors on the way: a feature-based efficient defense against textual backdoor attacks[C]// Findings of the Association for Computational Linguistics(EMNLP 2022). Stroudsburg: ACL, 2022: 668-683. |
| [46] | Li Jiazhao, Wu Zhuofeng, Ping Wei, et al. Defending against insertion-based textual backdoor attacks via attribution[C]// Findings of the Association for Computational Linguistics(ACL 2023). Stroudsburg: ACL, 2023: 8818-8833. |
| [47] | Chen Yu, Cao Qi, Zhang Kaike, et al. PKAD: pretrained knowledge is all you need to detect and mitigate textual backdoor attacks[C]// Findings of the Association for Computational Linguistics(EMNLP 2024). Stroudsburg: ACL, 2024: 5837-5849. |
| [48] | Wang Bolun, Yao Yuanshun, Shan S, et al. Neural cleanse: identifying and mitigating backdoor attacks in neural networks[C]// 2019 IEEE Symposium on Security and Privacy. New York: IEEE, 2019: 707-723. |
| [49] | Gao Yansong, Xu Chang, Wang Derui, et al. STRIP: a defence against trojan attacks on deep neural networks[C]// The 35th Annual Computer Security Applications Conference. New York: ACM, 2019: 113-125. |
| [50] | Shen Guangyu, Cheng Siyuan, Zhang Zhuo, et al. BAIT: large language model backdoor scanning by inverting attack target[C]// 2025 IEEE Symposium on Security and Privacy. New York: IEEE, 2025: 1676-1694. |
| [51] | Li Xi, Mao Ruofan, Zhang Yusen, et al. Chain-of-scrutiny: detecting backdoor attacks for large language models[C]// Findings of the Association for Computational Linguistics: ACL 2025. Stroudsburg: ACL, 2025: 7705-7727. |
| [52] | Liu Kang, Dolan-gavitt B, Garg S. Fine-pruning: defending against backdooring attacks on deep neural networks[C]// The 21st International Symposium on Research in Attacks, Intrusions, and Defenses. Heidelberg: Springer, 2018: 273-294. |
| [53] | Wei Chengkun, Meng Wenlong, Zhang Zhikun, et al. LMSanitator: defending prompt-tuning against task-agnostic backdoors[C]// The 31st Network and Distributed System Security Symposium. San Diego: NDSS, 2024: 1-8. |
| [54] | Jiang Peihai, Lyu Xixiang, Li Yige, et al. Backdoor token unlearning: exposing and defending backdoors in pretrained language models[C]// The 39th AAAI Conference on Artificial Intelligence. Palo Alto: AAAI, 2025: 24285-24293. |
| [55] | Truong V T, Le L B. Critical-CoT: a robust defense framework against reasoning-level backdoor attacks in large language models[C]// The 64th Annual Meeting of the Association for Computational Linguistics. Stroudsburg: ACL, 2026: 10823-10841. |
| [56] | Houlsby N, Giurgiu A, Jastrzebski S, et al. Parameter-efficient transfer learning for NLP[C]// The 36th International Conference on Machine Learning. Long Beach: PMLR, 2019: 2790-2799. |
| [57] | Dettmers T, Pagnoni A, Holtzman A, et al. QLoRA: efficient finetuning of quantized LLMs[C]// Advances in Neural Information Processing Systems 36. New York: NeurIPS, 2023: 10088-10115. |
| [58] | Abadi M, Chu A, Goodfellow I, et al. Deep learning with differential privacy[C]// The 2016 ACM SIGSAC Conference on Computer and Communications Security. New York: ACM, 2016: 308-318. |
| [59] | Gebru T, Morgenstern J, Vecchione B, et al. Datasheets for datasets[J]. Communications of the ACM, 2021, 64(12): 86-92. |
| [60] | Mitchell M, Wu S, Zaldivar A, et al. Model cards for model reporting[C]// The 2019 Conference on Fairness, Accountability, and Transparency. New York: ACM, 2019: 220-229. |
| [61] | Goodfellow I J, Shlens J, Szegedy C. Explaining and harnessing adversarial examples[EB/OL].(2014-12-19)[2026-05-22]. https://arxiv.org/pdf/1412.6572. |
| [1] | 聂豪杰, 孙德刚, 潘兴博, 万巍, 龙春. 面向大语言模型的成员推理攻击与防御技术综述[J]. 信息网络安全, 2026, 26(9): 1341-1353. |
| [2] | 宋铮, 杨芮淇, 李化成. 仓库级静态漏洞检测综述:从规则驱动到大语言模型与智能体[J]. 信息网络安全, 2026, 26(9): 1369-1382. |
| [3] | 吕昕晨, 尹士民. 面向大模型分布式微调的选择性聚合轻量化后门防御方法[J]. 信息网络安全, 2026, 26(7): 1001-1011. |
| [4] | 姚戊煌, 王佳鹏, 陈康冰, 郑之涵, 谭毓安. 基于指令翻译插桩的LLM辅助固件内存泄漏分析[J]. 信息网络安全, 2026, 26(7): 1087-1100. |
| [5] | 杨乔炀, 范希明, 贾鹏. 基于大语言模型的语义知晓的模糊测试驱动生成方案[J]. 信息网络安全, 2026, 26(7): 1128-1148. |
| [6] | 孙钰, 张轩瑞, 刘新宇. 高级持续性威胁检测与溯源研究进展[J]. 信息网络安全, 2026, 26(6): 833-853. |
| [7] | 苗博, 袁得嵛, 张腾, 杨懿, 黄赞. 基于思维链污染的检索增强生成后门攻击[J]. 信息网络安全, 2026, 26(6): 977-998. |
| [8] | 胡倾城, 张婉, 袁亚丽, 张静. 基于多视图知识增强的大语言模型事实型幻觉优化方法[J]. 信息网络安全, 2026, 26(5): 772-787. |
| [9] | 崔津华, 董亮, 杨新. 大语言模型推理隐私保护技术综述[J]. 信息网络安全, 2026, 26(4): 503-520. |
| [10] | 李岩, 杨文章, 薛吟兴. 基于LLM翻译与差分测试的跨语言编译器模糊测试[J]. 信息网络安全, 2026, 26(4): 591-604. |
| [11] | 胡勉宁, 李欣, 李明锋, 袁得嵛. 基于大语言模型的多策略增强中文网络威胁情报实体抽取研究[J]. 信息网络安全, 2026, 26(4): 615-625. |
| [12] | 袁明, 邹其霖, 袁文骐, 王群. 大语言模型提示词注入攻击与防御综述[J]. 信息网络安全, 2026, 26(3): 341-354. |
| [13] | 顾兆军, 李丽, 隋翯. 基于大语言模型的SQL注入漏洞检测载荷生成方法[J]. 信息网络安全, 2026, 26(2): 274-290. |
| [14] | 仝鑫, 焦强, 王靖亚, 袁得嵛, 金波. 公共安全领域大语言模型的可信性研究综述:风险、对策与挑战[J]. 信息网络安全, 2026, 26(1): 24-37. |
| [15] | 胡雨翠, 高浩天, 张杰, 于航, 杨斌, 范雪俭. 车联网安全自动化漏洞利用方法研究[J]. 信息网络安全, 2025, 25(9): 1348-1356. |
| 阅读次数 | ||||||
|
全文 |
|
|||||
|
摘要 |
|
|||||